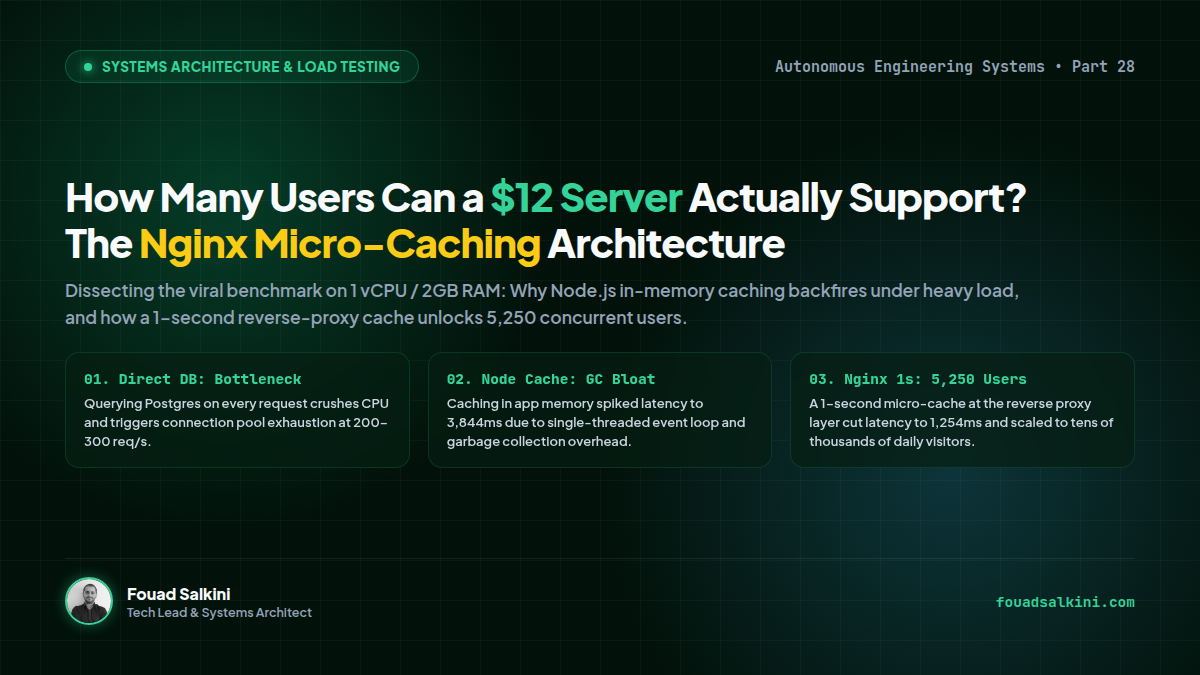
How Many Users Can a $12 Server Support? The Nginx Micro-Caching Architecture
Dissecting Arjay McCandless's viral load test on a 1 vCPU / 2GB RAM DigitalOcean droplet: why Node.js in-memory caching backfires under heavy load, and how a 1-second Nginx micro-cache unlocks 5,250 concurrent users and tens of thousands of daily visitors.
A viral benchmark video by software engineer Arjay McCandless (@arjay_the_dev) recently caught the attention of hundreds of thousands of developers with a deceptively simple question:
“How many users can a $12 server actually support?”
In an era where startup pitch decks routinely budget thousands of dollars a month for multi-region Kubernetes clusters, managed database replicas, and redundant serverless functions before acquiring their first hundred users, Arjay’s experiment offers a refreshing, grounded reality check in systems engineering fundamentals.
Using Grafana k6 running on a separate 4 vCPU / 8GB load-testing instance across a sub-millisecond local network link, Arjay pushed an entry-level $12/month DigitalOcean droplet (1 vCPU, 2GB RAM, Ubuntu 24.04) to its physical breaking point.
Here is an architectural deconstruction of what happened, why application-level caching backfired, and how a 1-second Nginx micro-cache allowed a $12 box to serve 5,250 concurrent users and tens of thousands of daily active visitors.
1. The Benchmark Topology
The experiment modeled a classic full-stack web application:
- Frontend Reverse Proxy: Nginx.
- Backend API: Node.js (Express/Fastify) exposing a
GET /feedendpoint. - Database: PostgreSQL storing user posts and feeds.
- Load Generator: Dedicated 4 vCPU / 8GB RAM Droplet running Grafana k6 in the same datacenter (
< 1 msround-trip latency).
                      [ Grafana k6 Generator ]
                       (4 vCPU · 8GB · <1ms)
                                │
                        2,500 - 5,250 VUs
                                │
                                ▼
                       [ Nginx Reverse Proxy ]
                                │
               ┌────────────────┴────────────────┐
               │                                 │
     (Direct Pass-through)               (1s Micro-Cache)
               ▼                                 ▼
      [ Node.js Application ]          [ Return from Proxy RAM ]
               │                          (No App / No DB Load!)
               ▼
     [ PostgreSQL Database ]
2. Stage 1: The Raw Baseline (Direct DB Query)
In the uncached baseline scenario, every incoming HTTP request triggered a SQL query against PostgreSQL to assemble the dynamic feed.
- Target Load: 2,500 simulated concurrent users.
- Observed Throughput: Leveled off at roughly 222 to 232 requests per second.
- Average Response Latency: 2,476 ms (nearly 2.5 seconds!).
- Failure Mode: PostgreSQL connection pool exhaustion and high CPU context switching. On a single vCPU machine, splitting CPU cycles between Nginx TLS termination, Node.js event-loop scheduling, and PostgreSQL query execution created an insurmountable bottleneck.
3. Stage 2: The Trap of Application-Level Caching (Node.js RAM)
Most developers’ first instinct when a database slows down is to add an in-memory dictionary or LRU cache inside their application code:
// The Naive Application Cache Trap
const cache = new Map();

app.get('/feed', async (req, res) => {
  const cached = cache.get('global_feed');
  if (cached && Date.now() - cached.time < 1000) {
    return res.json(cached.data);
  }
  const data = await db.query('SELECT * FROM posts ORDER BY created_at DESC LIMIT 20');
  cache.set('global_feed', { data, time: Date.now() });
  res.json(data);
});
The result? Performance got worse, not better.
- Observed Latency Spiked to: 3,844 ms (a 55% degradation compared to the baseline!).
- Why did this happen?
- Single-Threaded Event Loop Contention: Node.js runs on a single event-loop thread. When 2,500 concurrent connections hit Node.js, the V8 engine spent massive compute cycles serializing JSON strings, managing Map lookups, and allocating memory buffers.
- V8 Garbage Collection (GC) Thrashing: Rapidly creating and discarding thousands of response objects triggered frequent Stop-The-World minor and major GC pauses, causing latency spikes across all active requests.
4. Stage 3: The Secret Weapon — Nginx 1-Second Micro-Caching
Instead of letting requests ever touch Node.js or JavaScript runtime memory, the caching logic was moved upstream directly into the Nginx reverse proxy using a technique known as Micro-caching:
# /etc/nginx/nginx.conf
proxy_cache_path /var/cache/nginx levels=1:2 keys_zone=FEED_CACHE:10m max_size=100m inactive=10m;

server {
    listen 80;
    server_name api.example.com;

    location /feed {
        proxy_cache FEED_CACHE;
        proxy_cache_valid 200 1s;          # Cache valid responses for exactly 1 second
        proxy_cache_use_stale updating;   # Serve stale cache while fetching updates
        proxy_cache_lock on;              # Prevent cache stampedes (thundering herd)

        proxy_pass http://127.0.0.1:3000;
        add_header X-Cache-Status $upstream_cache_status;
    }
}
The Architectural Magic of 1 Second:
For a social feed or dynamic dashboard, users do not care if a feed is 800 milliseconds old. But to a computer server receiving 2,000 requests every second:
- Request #1 hits Node.js and Postgres.
- Requests #2 through #2,000 within that second are served directly from Nginx’s C-based memory buffer in micro-seconds.
- Node.js and PostgreSQL only do work once per second!
The Results:
- Response Latency Dropped to: 1,254 ms (a ~50% drop from baseline, and ~67% drop from Node cache).
- Stable Concurrency Scaled to: 5,250 simultaneous active users without dropping packets.
5. From Concurrency to Reality: What Does 5,250 Concurrents Mean?
Junior engineers frequently conflate Concurrent Users with Total Registered Users or Daily Active Users (DAU).
In production consumer web applications:
- Users do not click simultaneously every single millisecond. They read, scroll, pause, and navigate.
- A standard industry rule of thumb is that at peak traffic hours, only 5% to 10% of total active daily users are issuing requests at the exact same instant.
Formula:
Daily Active Users (DAU) = Peak Concurrent Users / Concurrency Ratio (5% - 10%)

At 5,250 Concurrent Users:
• Conservative (10% ratio): 5,250 / 0.10 = 52,500 DAU
• Typical (5% ratio):       5,250 / 0.05 = 105,000 DAU
A humble $12 VPS with disciplined systems engineering and proxy-level micro-caching can comfortably handle a product with 50,000 to 100,000 daily active users.
6. Architectural Lessons for Modern Engineers
- Don’t cache in app memory if your proxy can do it faster: Nginx is written in C and optimized for event-driven asynchronous I/O with zero garbage collection overhead. Offload caching to Nginx before tuning application code.
- Beware the Thundering Herd: Use
proxy_cache_lock onandproxy_cache_use_stale updatingso that when a cache key expires, only one upstream request refreshes it while all others receive the stale buffer. - Scale vertically before horizontally: Before spending hundreds of dollars on managed Kubernetes clusters, load balancers, and multi-tenant read replicas, ensure your single-box architecture is actually extracting 100% of its hardware capability.
Written by Fouad Salkini (فؤاد سلقيني)
General Manager & Tech Lead at Tripnologies and Sync Studios. Systems Architect focusing on AI coding agents, DevOps, and quantitative systems.